Highlight
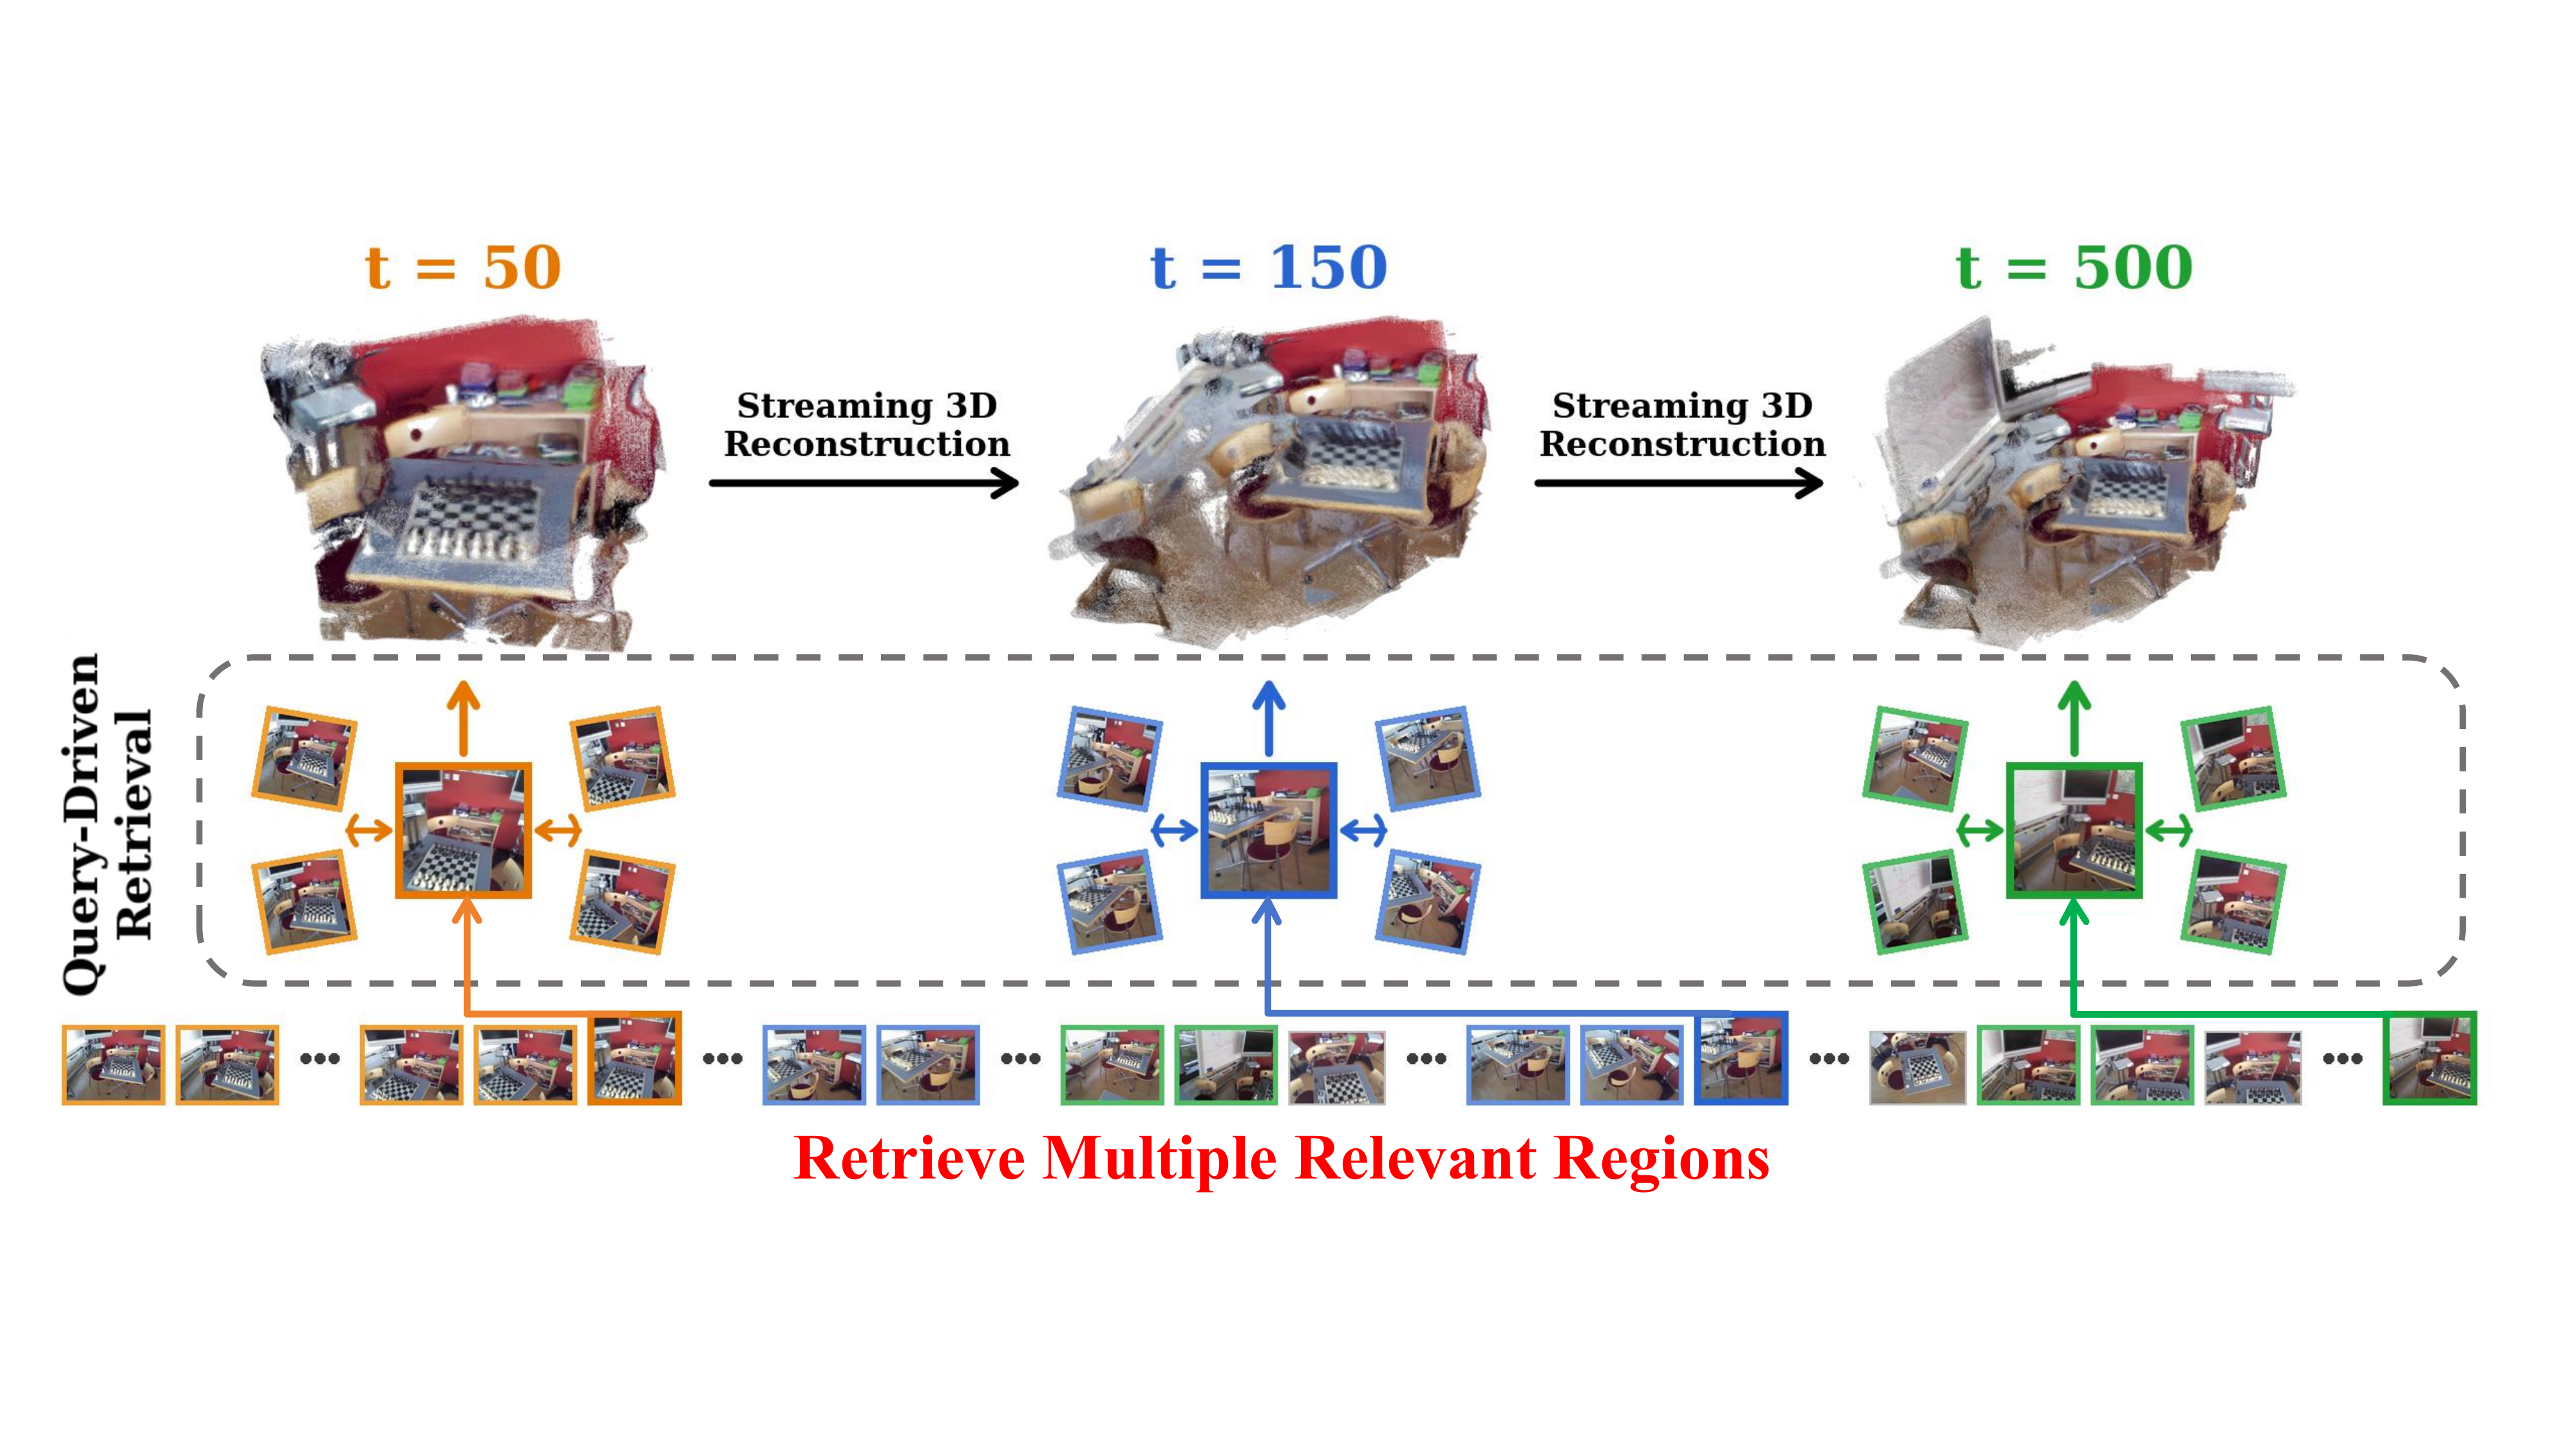
Visual Geometry Grounded Transformer (VGGT) advances 3D reconstruction via scalable Transformer architecture, but the quadratic complexity of global attention prevents long context application. StreamVGGT enables streaming with causal attention, yet its KV cache grows linearly with frames, causing memory overflow and quality degradation. We present RetrieveVGGT, a training-free framework, which formulates context construction for VGGT as a retrieval problem. By retrieving a fixed number of relevant frames at each step, VGGT maintains a controllable memory budget, which is close to its training context length. Interestingly, we find that the similarity between current frame queries and cached history frame keys at the first global attention layer of VGGT is already a strong indicator of relevance, eliminating the need for additional learned scoring. To enhance information diversity similar to a recommender system, we propose Segment Sampling so that the retrieval spans distinct relevant segments rather than a single high-similarity region. We design a pose-aware spatial memory mechanism that organizes history frames according to their already estimated camera poses, enabling location-aware retrieval. Extensive experiments demonstrate that RetrieveVGGT achieves state-of-the-art performance, outperforming StreamVGGT, TTT3R, and InfiniteVGGT while maintaining constant memory usage regardless of sequence length. Code is available at https://github.com/zzctmd/RetrieveVGGT.
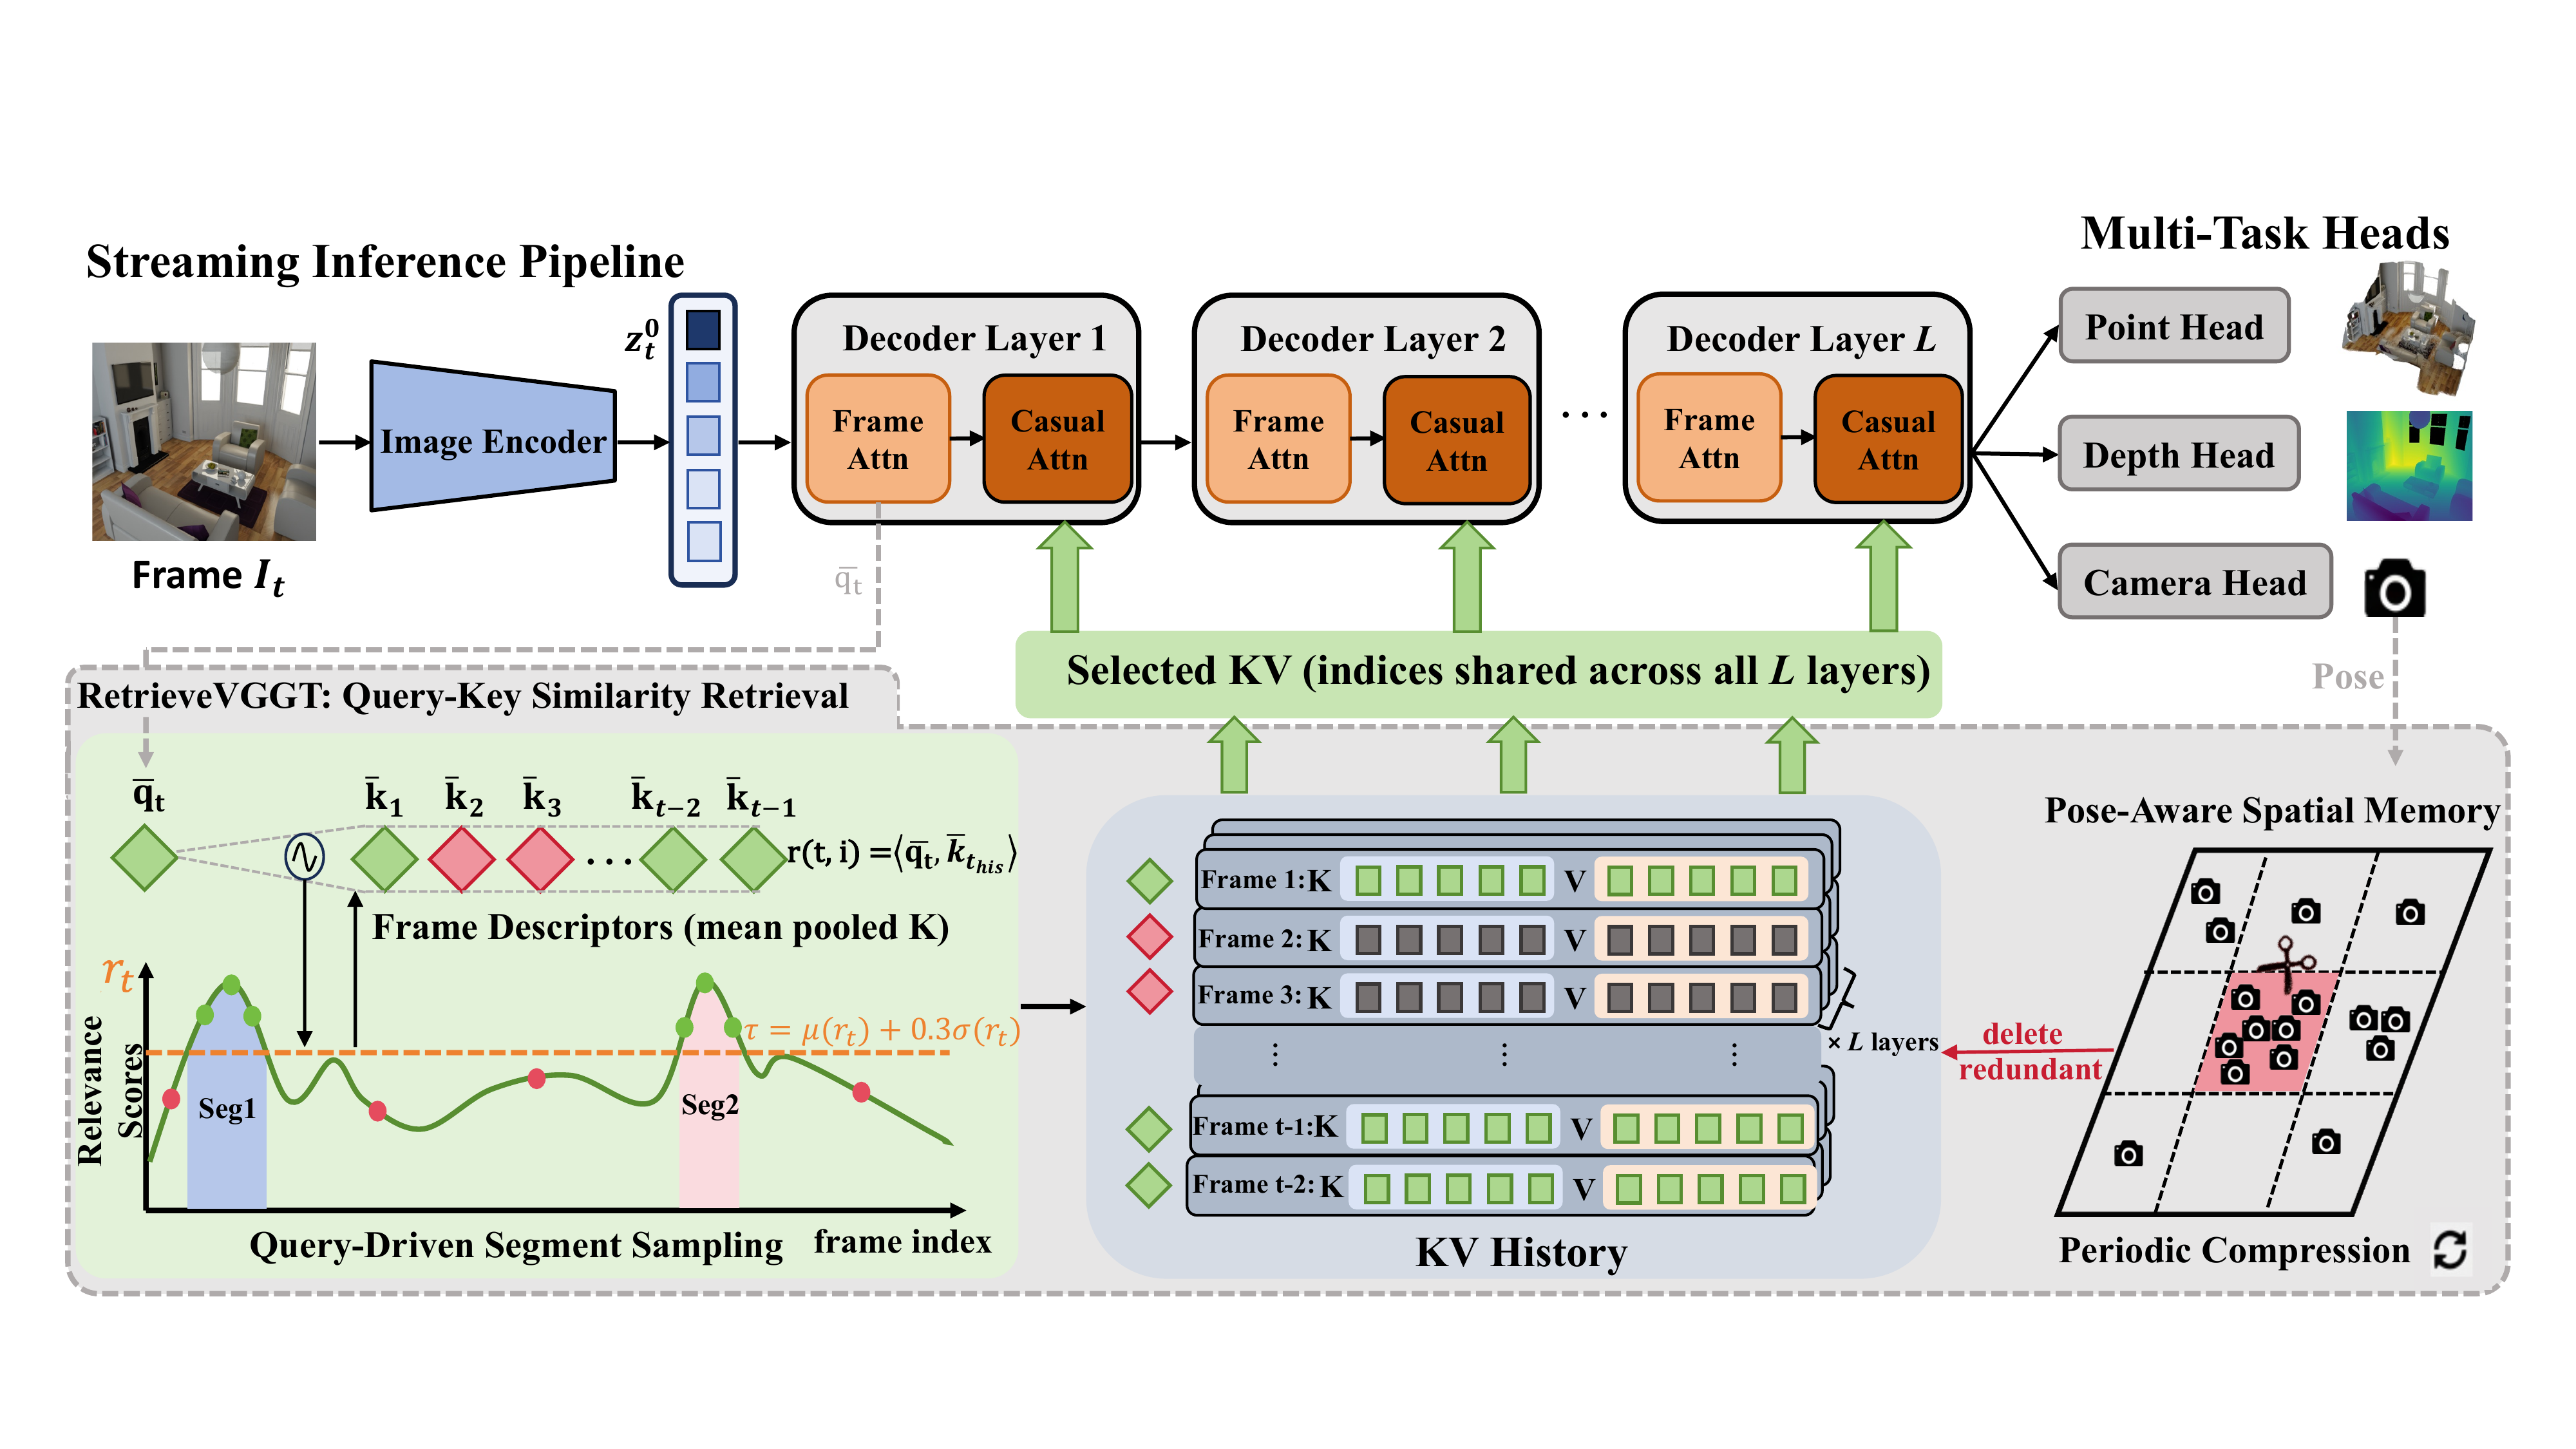
Given a query frame, RetrieveVGGT computes frame-level relevance scores using the dot product between query tokens and cached key tokens at the first global attention layer of VGGT. Segment Sampling then groups high-relevance frames into contiguous segments and selects one representative from each segment, ensuring temporal diversity. A pose-aware spatial memory further organizes cached frames by camera pose, enabling scalable long-term memory management with constant GPU consumption.
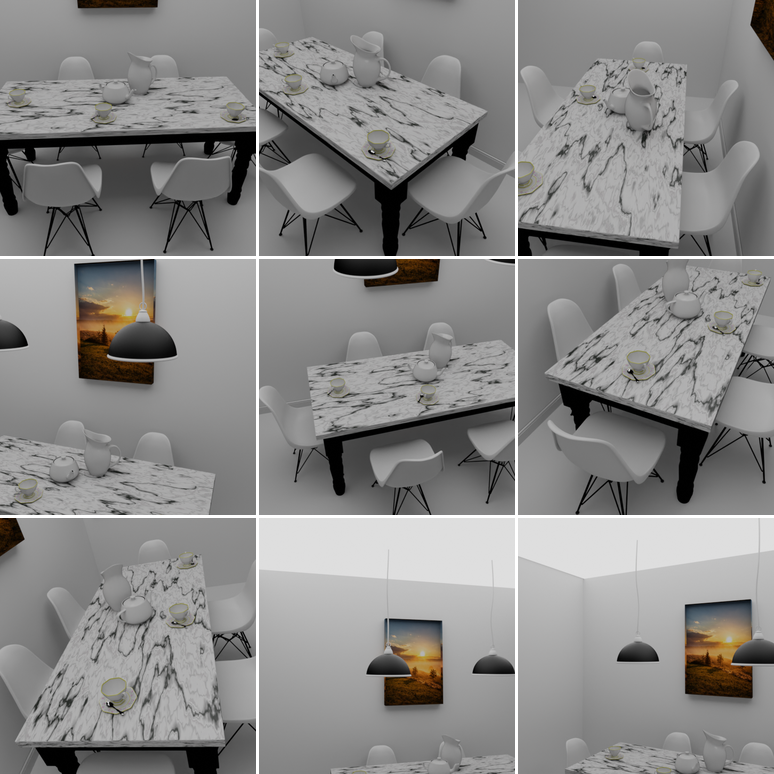
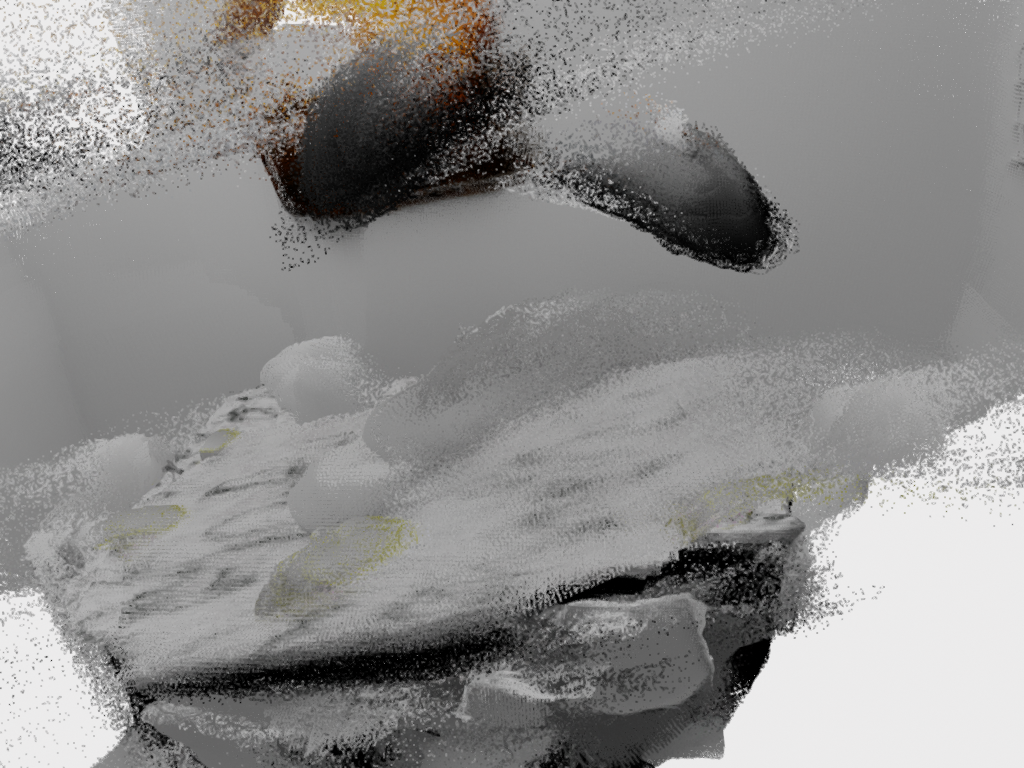
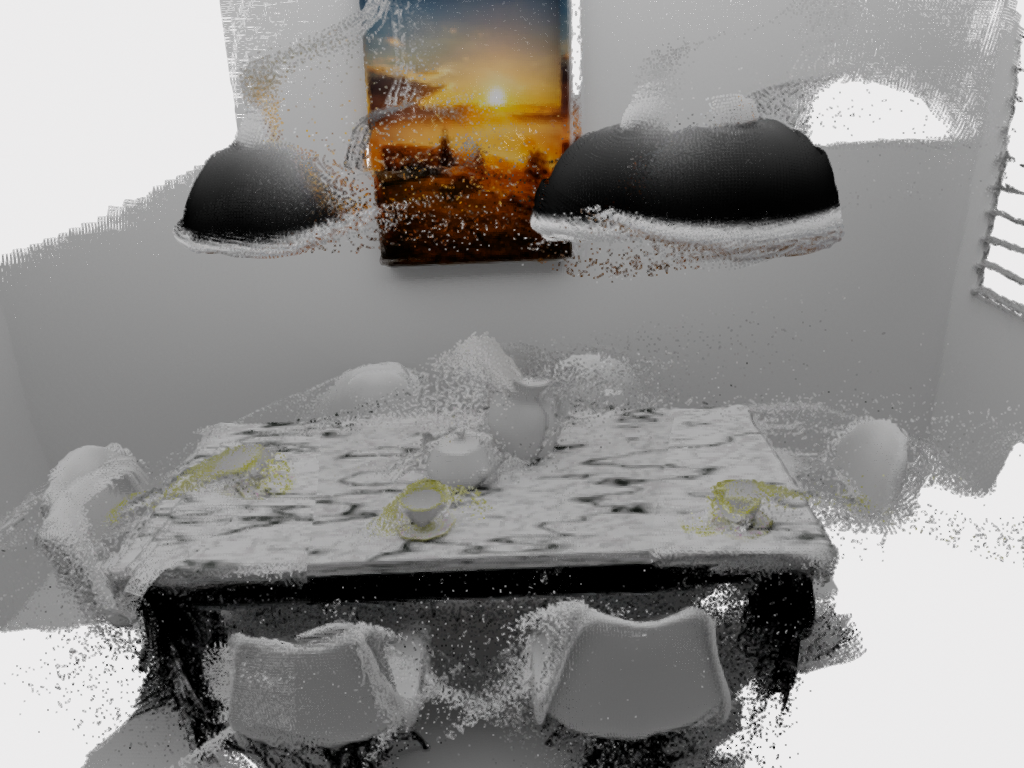
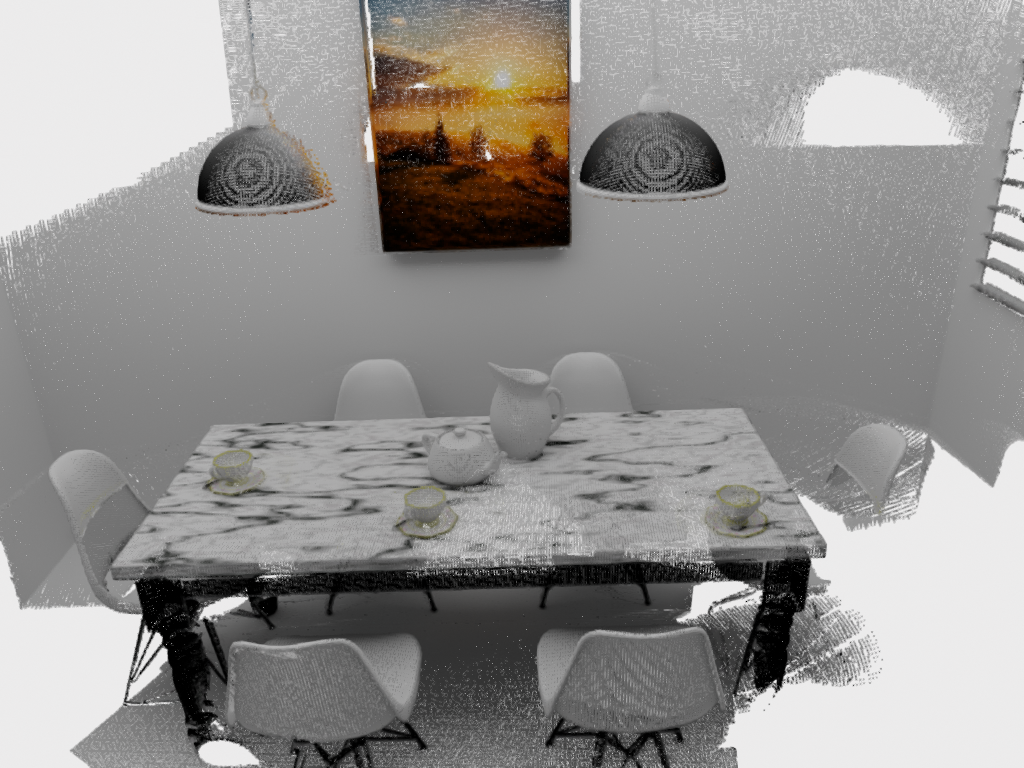
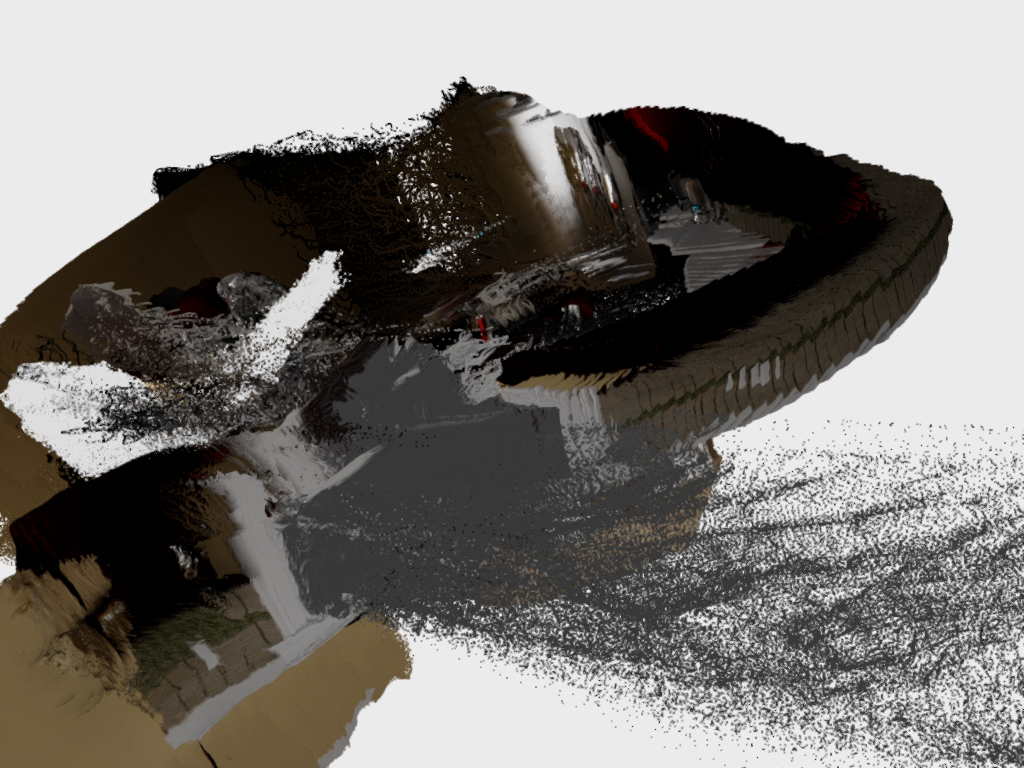
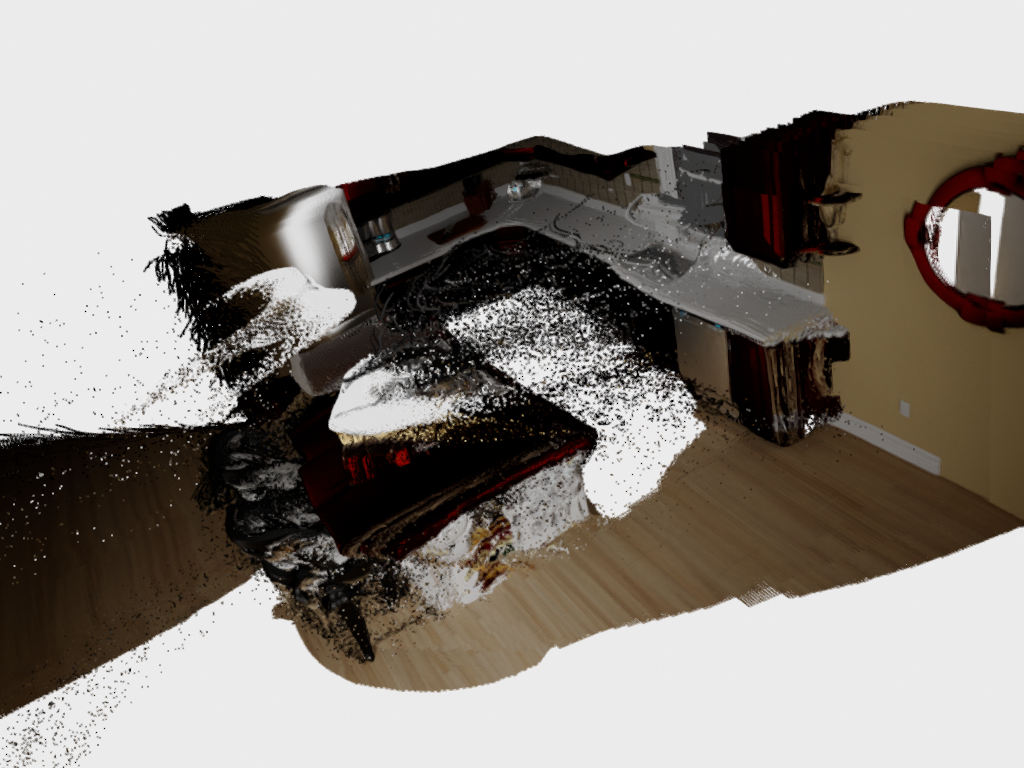
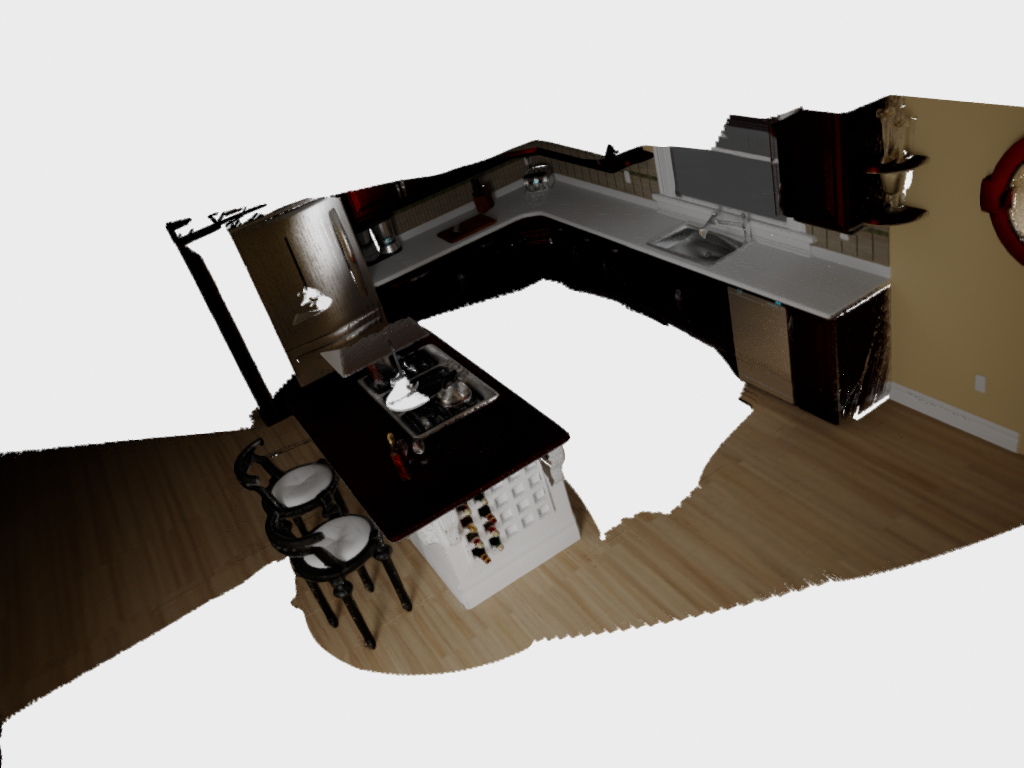
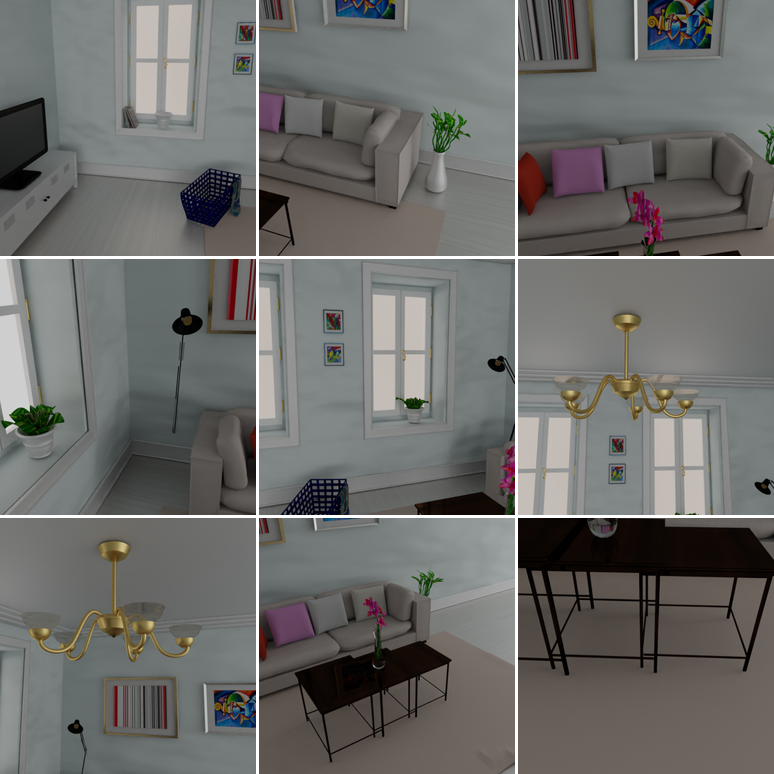
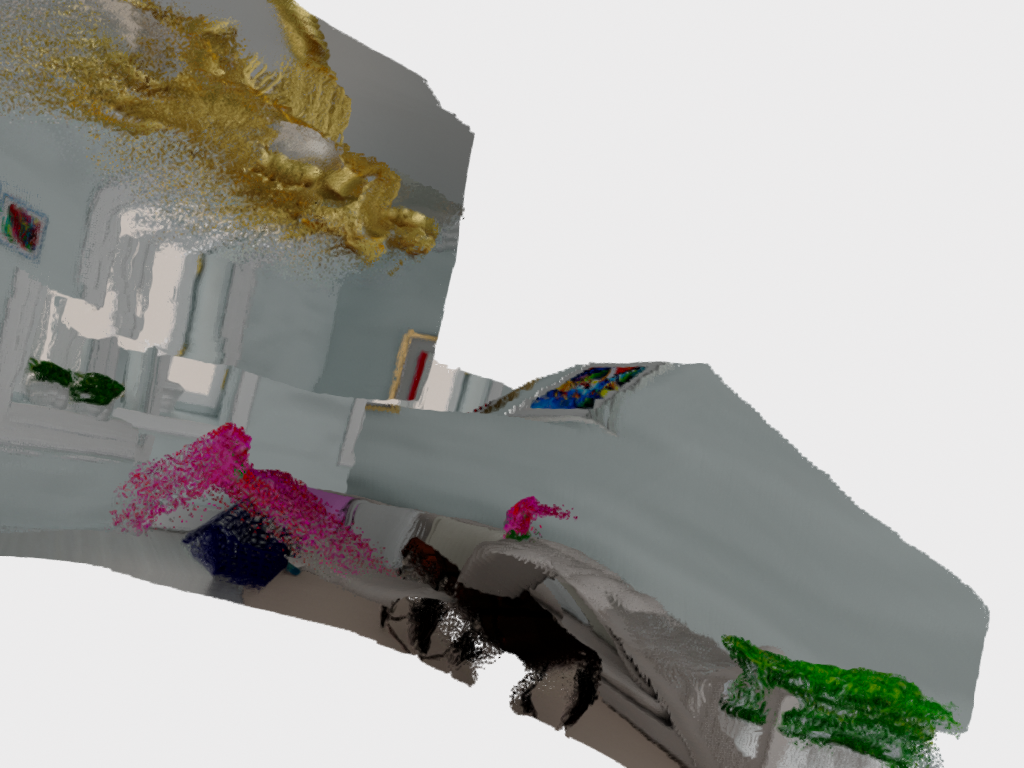
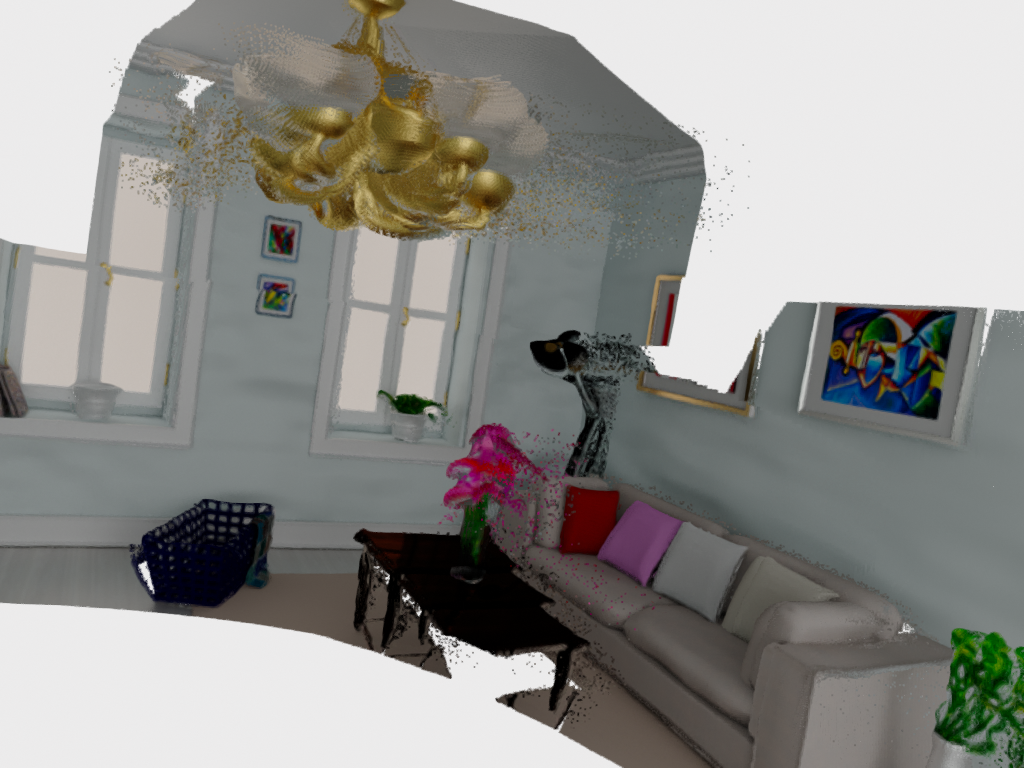
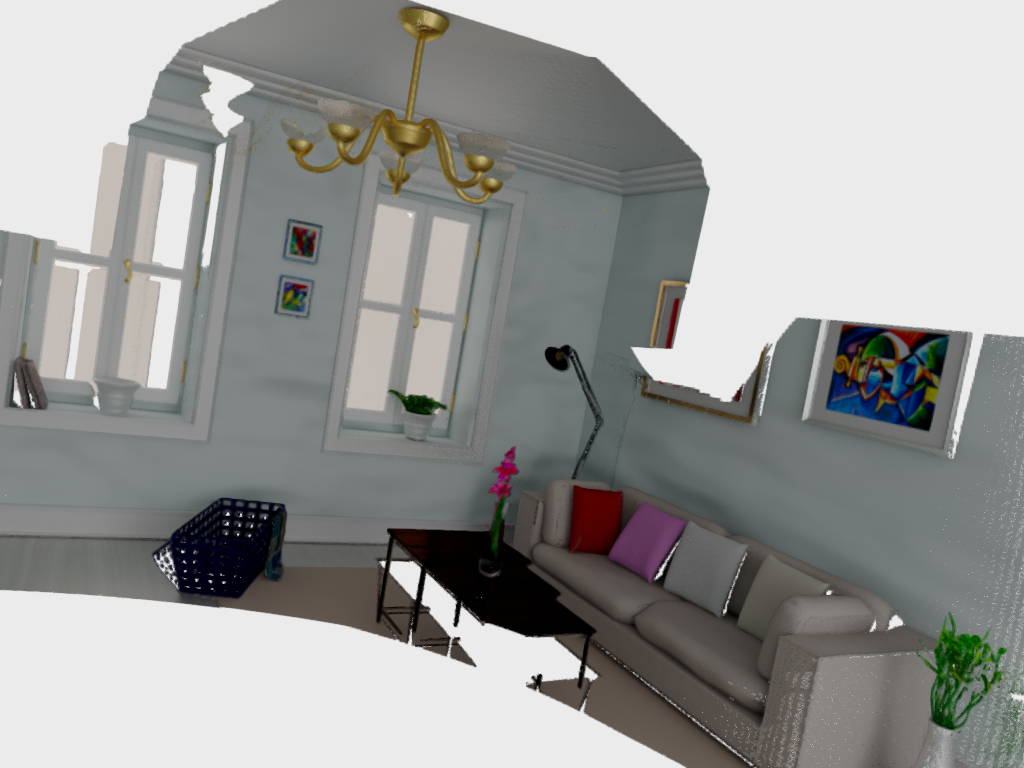
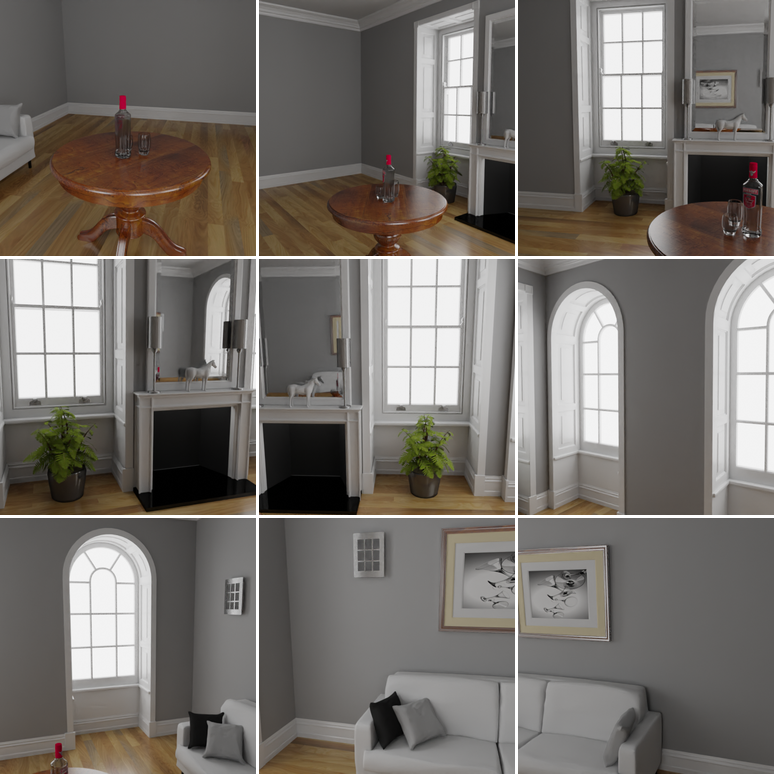
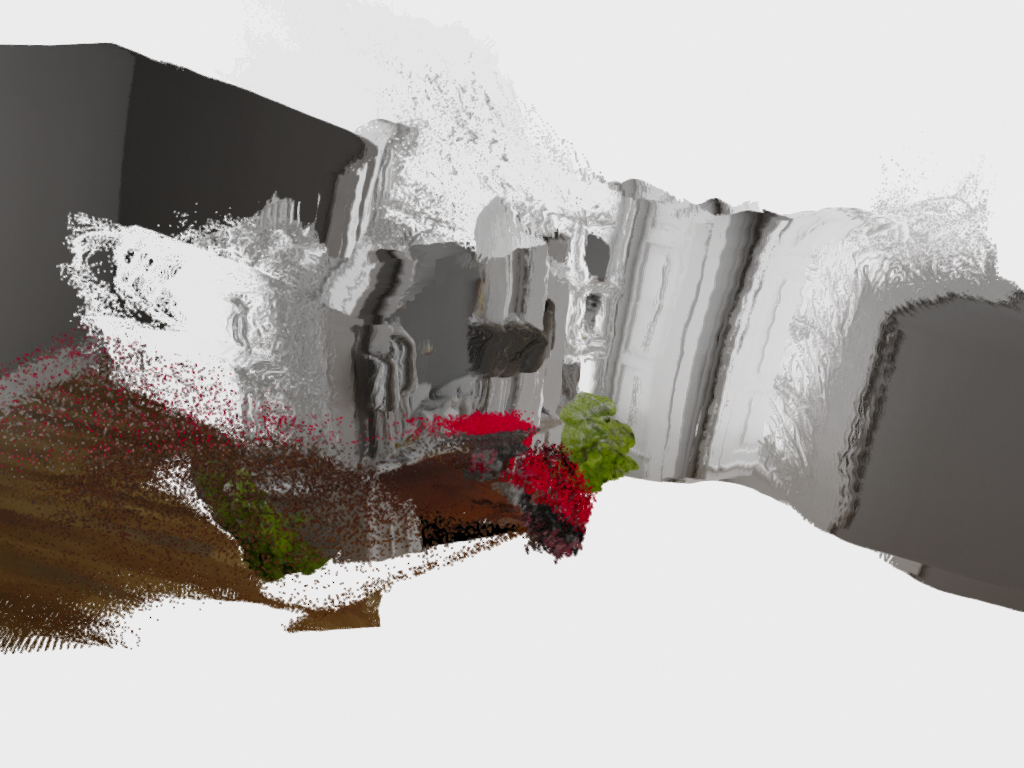
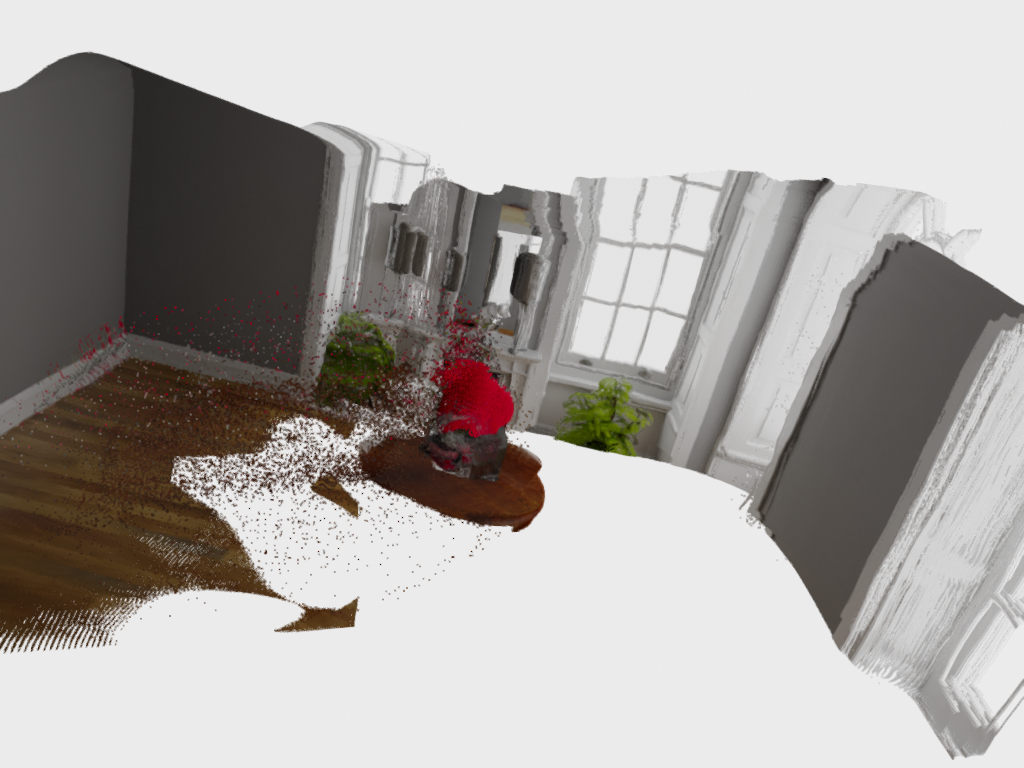
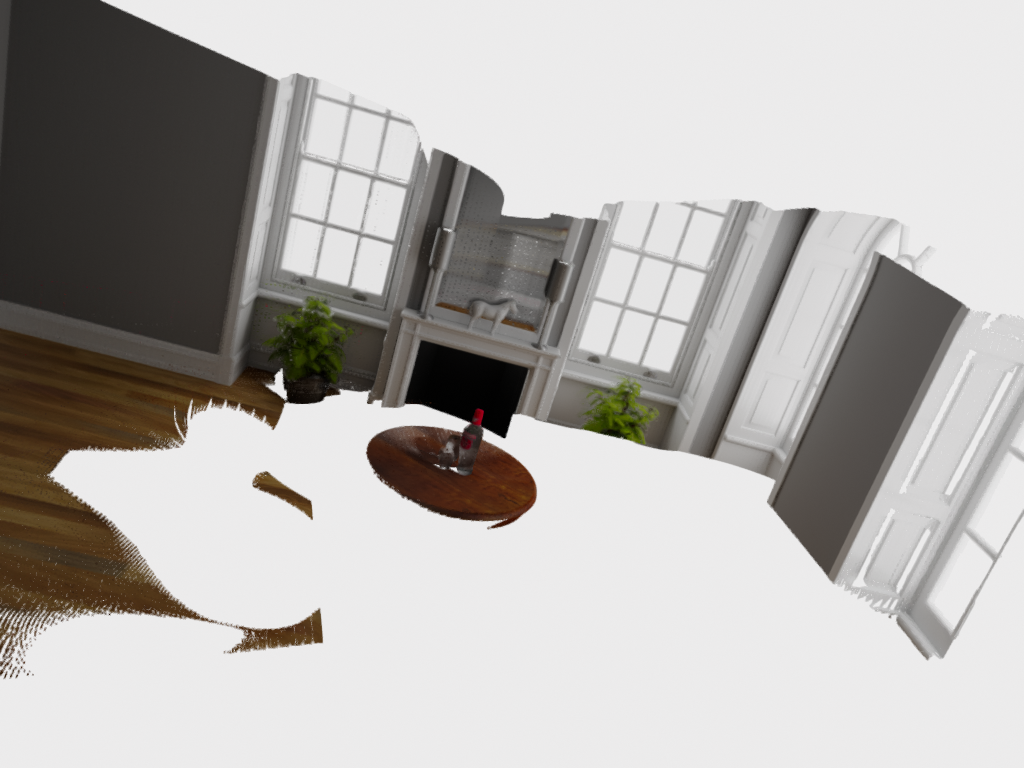
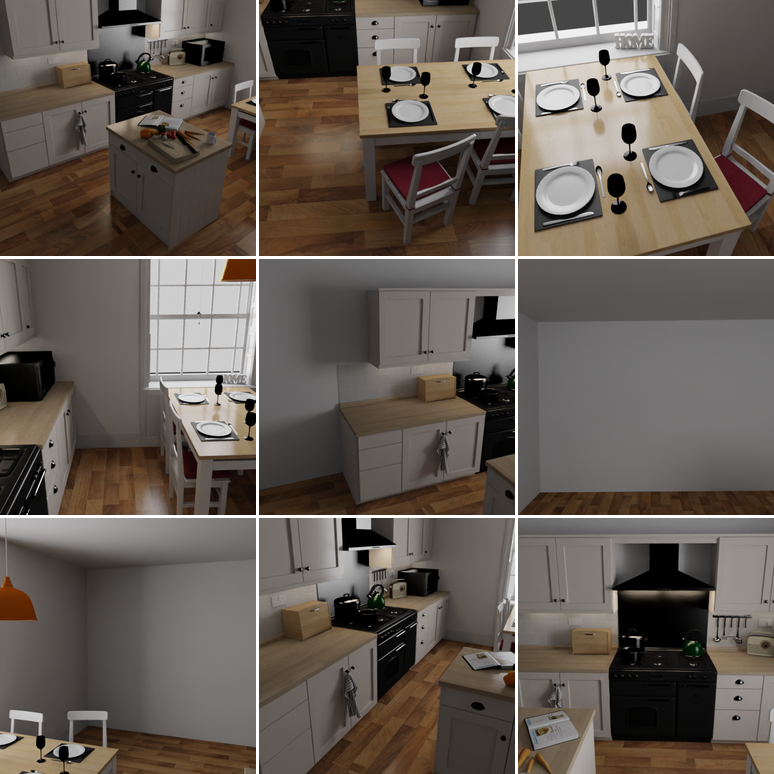
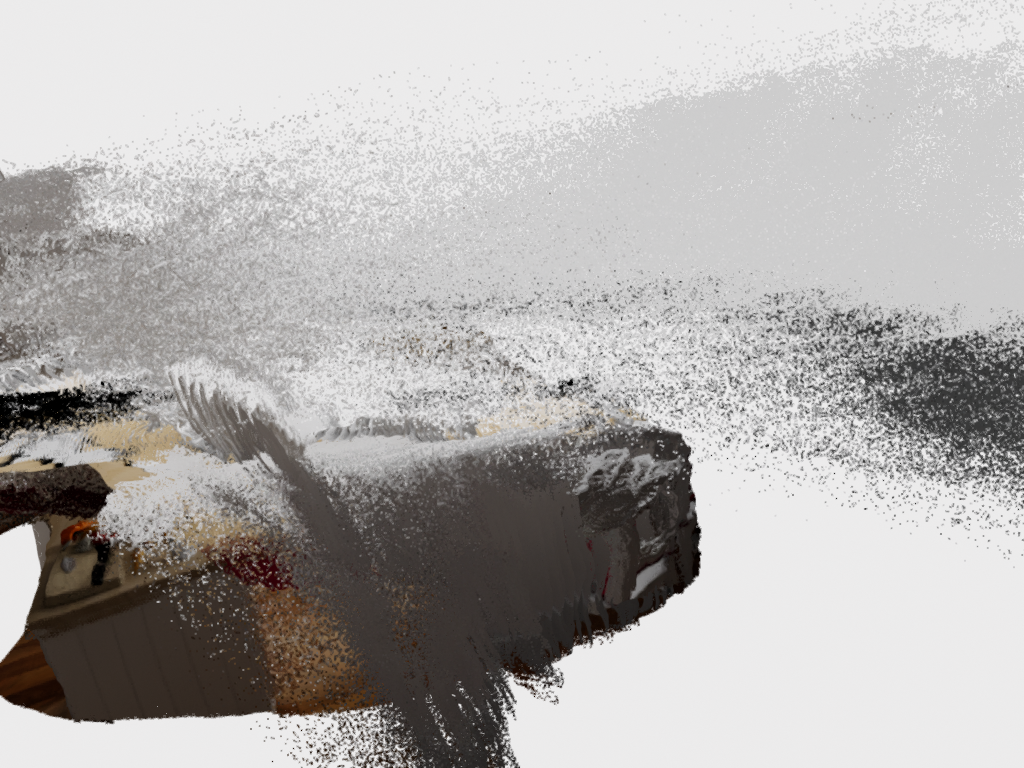
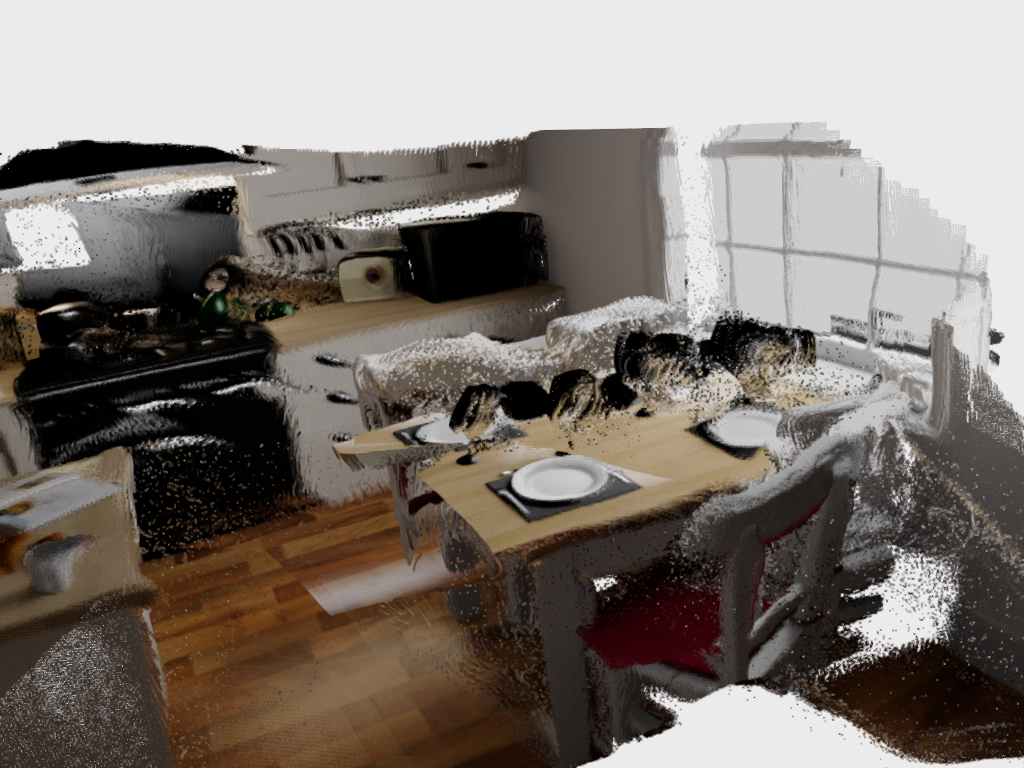
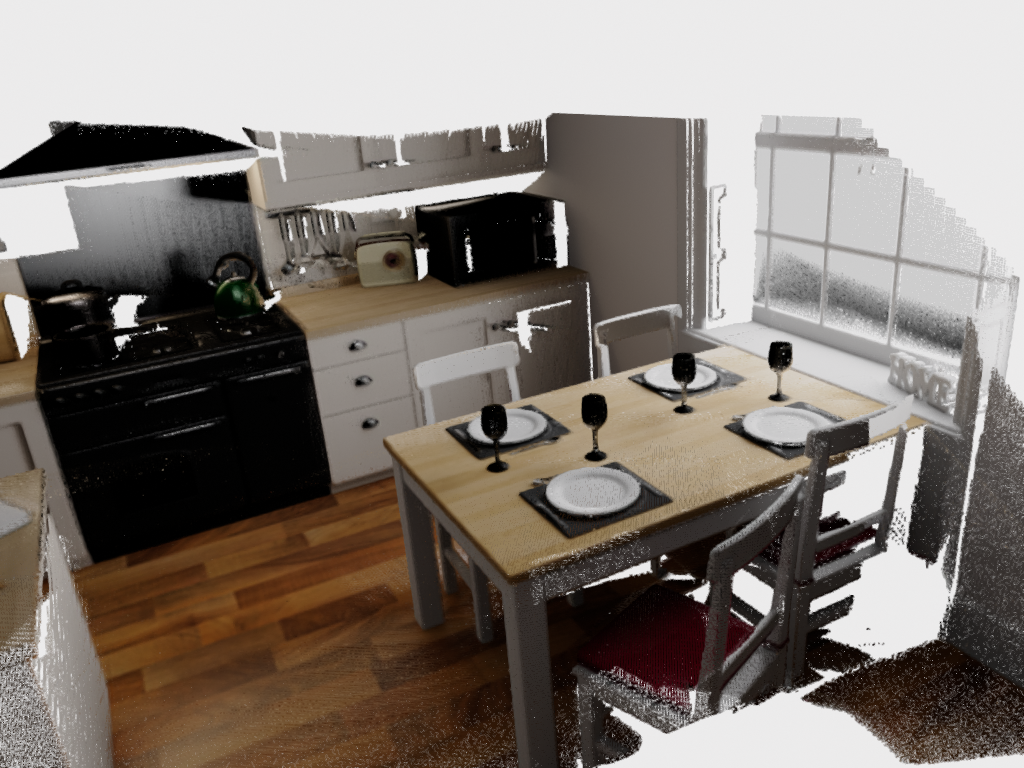
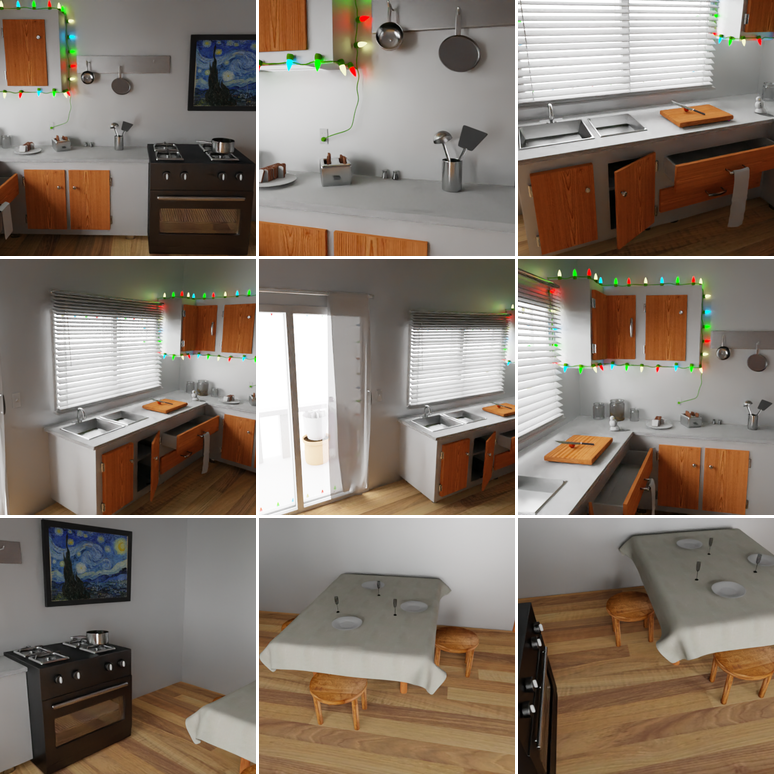
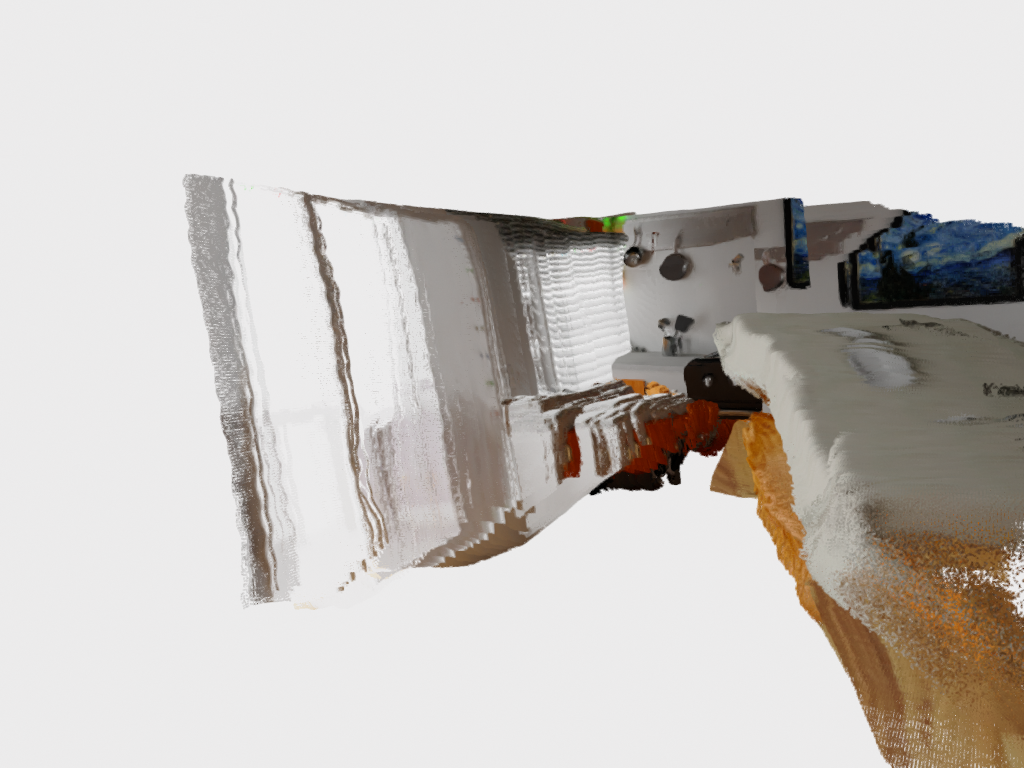
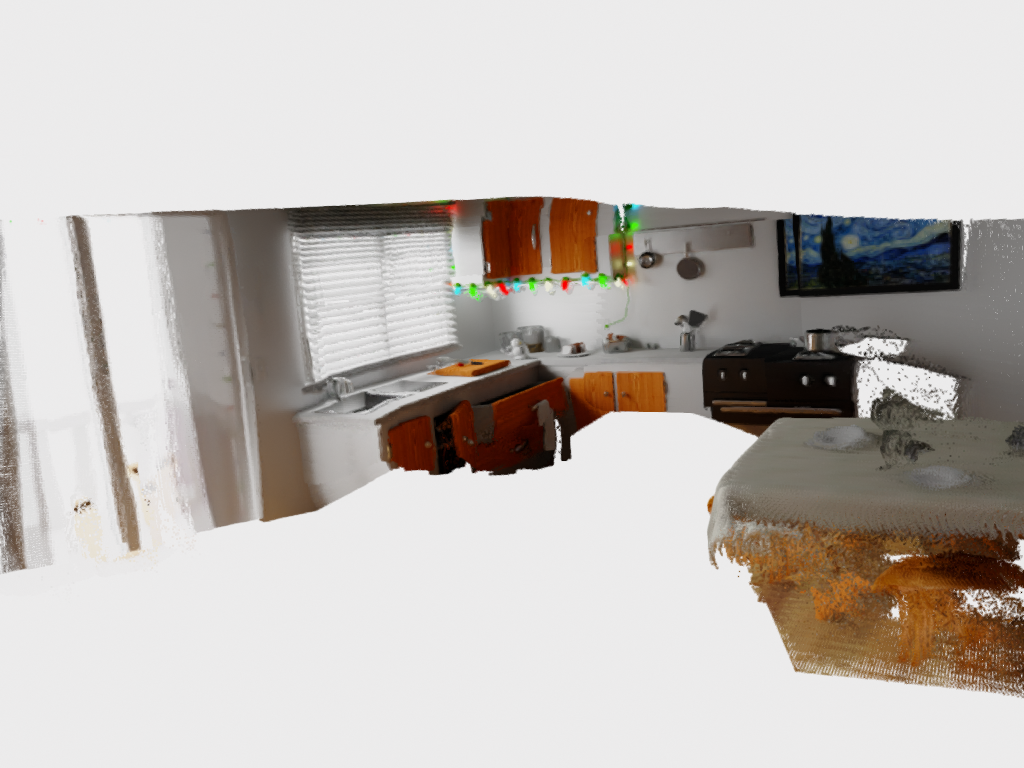
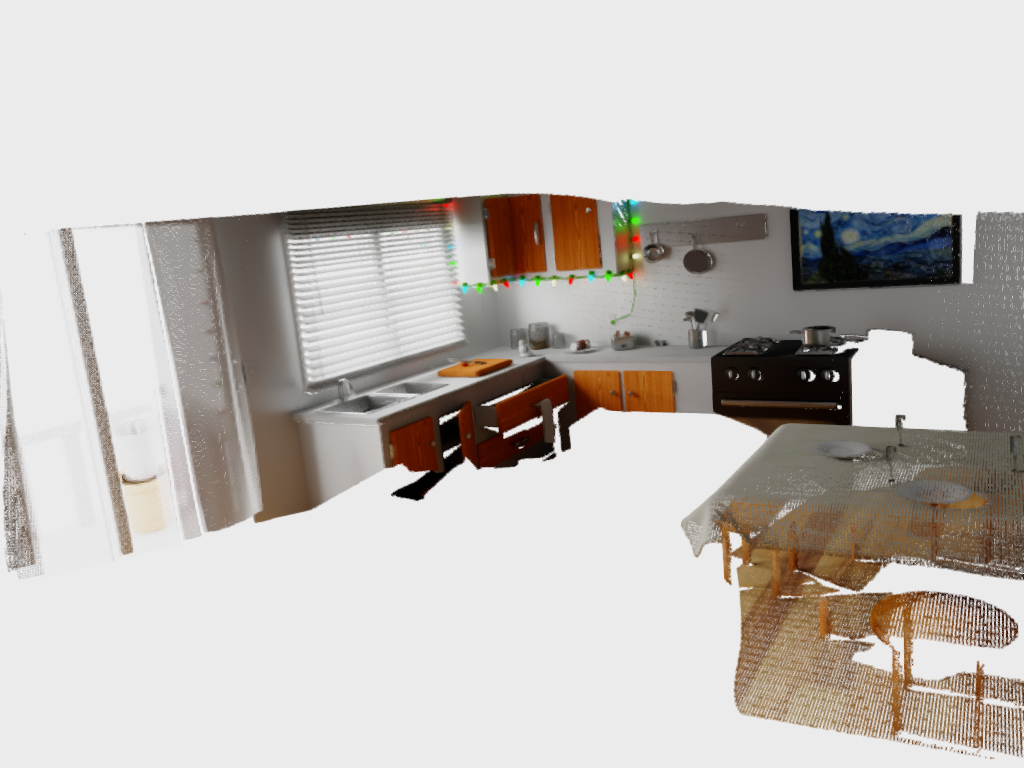
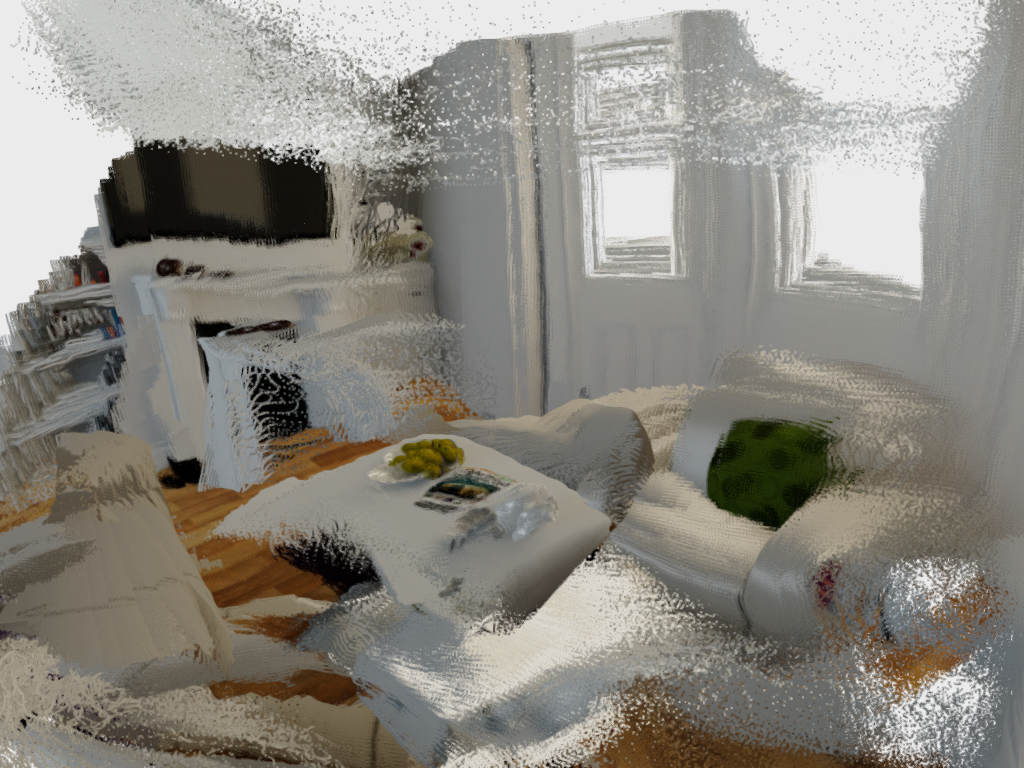
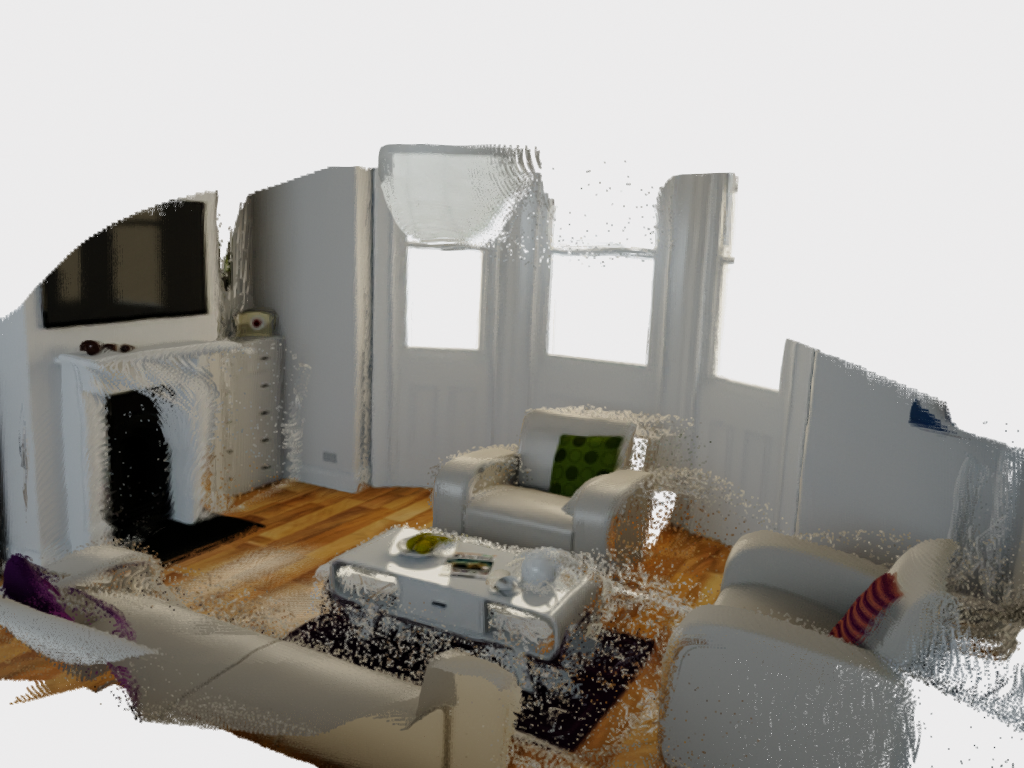
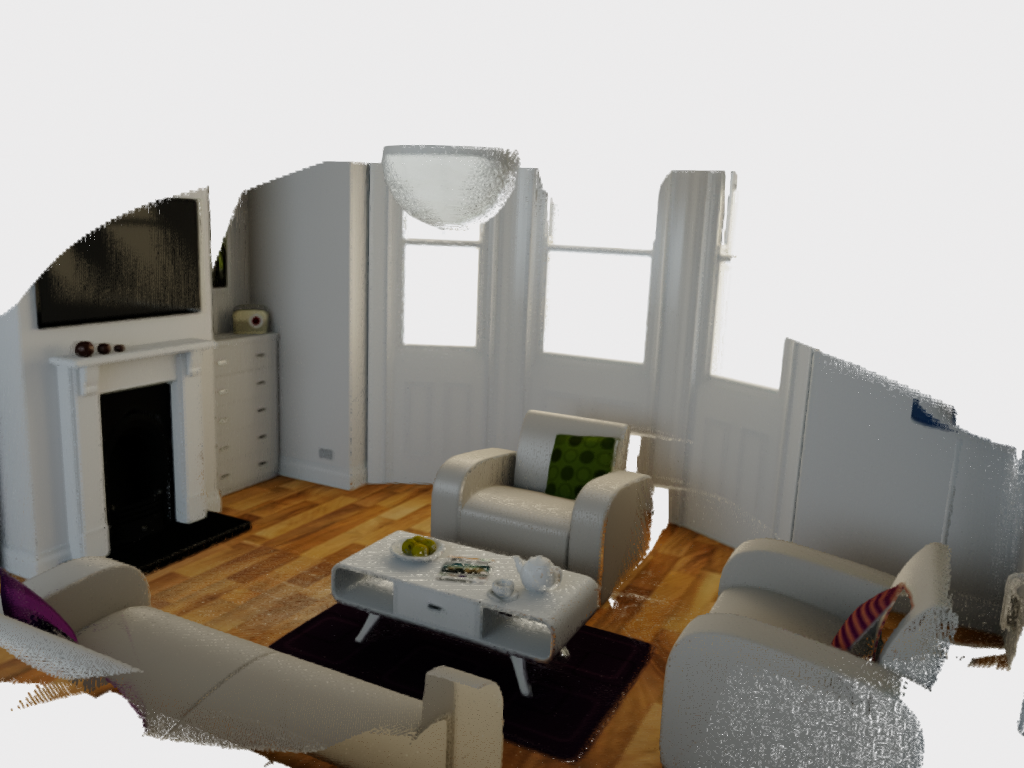
Qualitative 3D reconstruction results on NRGBD scenes. For each scene, we show the reference input, predictions from TTT3R and RetrieveVGGT (Ours), and the ground truth from an identical viewpoint. RetrieveVGGT maintains structural fidelity without the distortion or catastrophic forgetting seen in recurrent methods, particularly in large-scale scenes where long-range context is critical.
@inproceedings{zou2026retrievevggt,
  title={RetrieveVGGT: Training-Free Long Context Streaming 3D Reconstruction via Query-Key Similarity Retrieval},
  author={Zou, Zichen and Jia, Xiaosong and Wu, Zuxuan and Jiang, Yu-Gang},
  booktitle={NeurIPS},
  year={2026}
}